Data Engineering Roadmap 2026: Skills, Tools and Courses
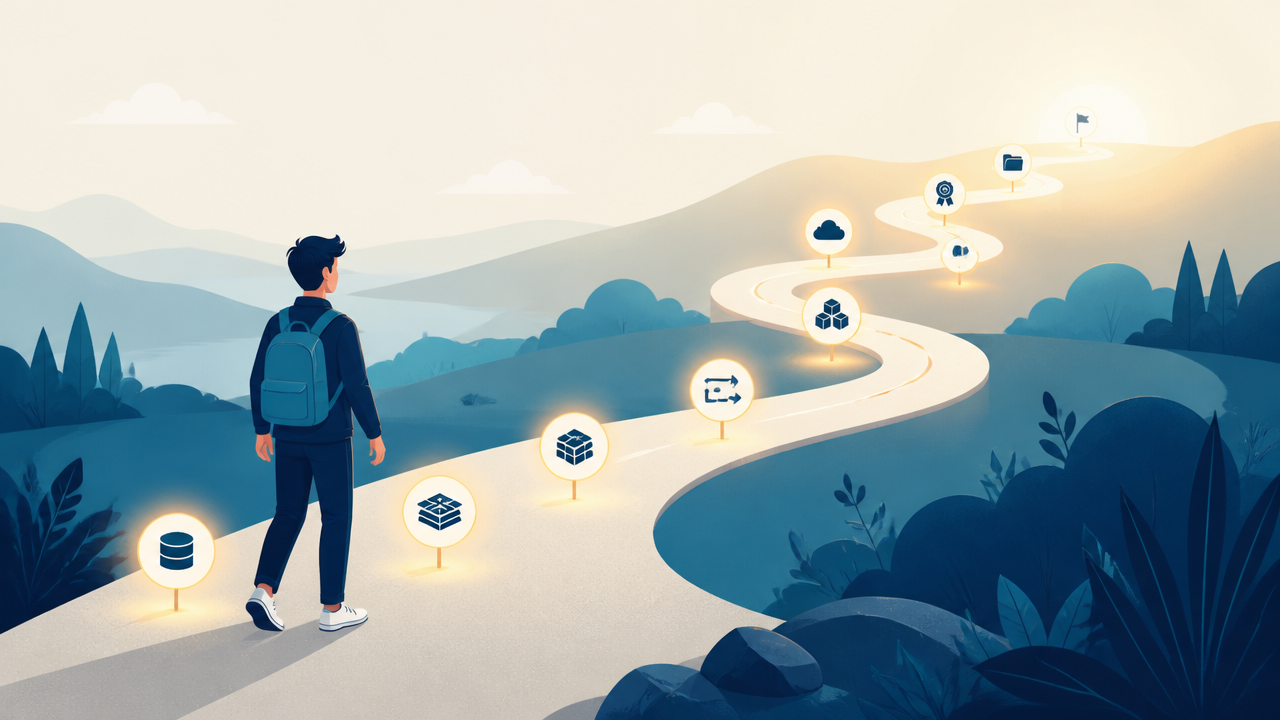
Data engineering is one of the more structured career paths in data — the skill stack is well-defined, and the order you learn it in genuinely matters. This roadmap covers the stages in the sequence that builds correctly, with course recommendations at each step.
Stage 1: SQL and Python Fundamentals (Weeks 1–6)
Everything downstream assumes strong SQL and working Python. Data engineers write more SQL day-to-day than most other data roles, and Python is the standard language for pipeline code. See our SQL roadmap for the staged SQL path specifically.
Stage 2: Data Modeling and Warehousing (Weeks 6–9)
Learn dimensional modeling — star schemas, fact and dimension tables, slowly changing dimensions — and warehouse fundamentals. This is the conceptual foundation for organizing data so it's fast to query and easy to maintain, and it shapes every pipeline you build afterward.
Stage 3: ETL/ELT and Pipeline Orchestration (Weeks 9–13)
Learn to build and schedule data pipelines — extracting from sources, transforming data reliably, and loading it into a warehouse. Apache Airflow is the most widely used orchestration tool and a reasonable default to learn first. Introduction to Data Engineering covers these fundamentals directly.
Stage 4: SQL-Based Transformation with dbt (Weeks 13–16)
dbt (data build tool) has become a near-standard part of the modern data stack for transforming data inside the warehouse using version-controlled SQL. See our What Is dbt? explainer if you're unfamiliar with why this tool has become so widely adopted so quickly.
Learn Apache Spark fundamentals for processing data at a scale beyond what a single machine or a standard SQL warehouse handles comfortably. Not every data engineering role needs deep Spark expertise, but foundational familiarity is increasingly expected, particularly at larger companies.
Pick one major cloud platform — AWS, Azure, or Google Cloud — based on your target job market, and go deep on its data services (S3/Glue/Redshift for AWS, Data Factory/Synapse for Azure, BigQuery/Dataflow for GCP). Trying to learn all three simultaneously spreads your effort too thin; depth on one platform is more valuable to employers than shallow familiarity with several.
Stage 7: A Structured Certificate (Weeks 23–28)
Once you have hands-on foundation across the stages above, a structured program consolidates the full stack and provides a credential. The IBM Data Engineering Professional Certificate covers Python, SQL, ETL, warehousing, and Spark in one comprehensive program — a strong choice specifically because it reinforces everything from the earlier stages rather than teaching isolated new content.
Stage 8: Portfolio Project (Weeks 28–32)
Build one complete, end-to-end pipeline project: ingest real (or realistic) data from a source, transform it through a proper pipeline with orchestration, load it into a warehouse with a sensible dimensional model, and document the design decisions. This is what recruiters and hiring managers actually want to see — not isolated exercises in each individual tool, but evidence you can design and build a working system.
What's Often Missing From Self-Taught Paths
Data quality and testing practices. Real pipelines need validation — catching bad data before it corrupts downstream reports — and this is frequently skipped in self-directed learning that focuses only on the happy path.
Understanding cost implications. Cloud data processing costs money, and understanding how pipeline design choices affect cost is a practical skill that separates junior from more experienced engineers.
Version control and CI/CD basics for data pipelines. Treating pipeline code with the same engineering discipline as application code — version control, testing, deployment practices — is increasingly expected, not optional.
A Realistic Timeline
Following this roadmap at 8–10 hours a week, expect 7–8 months from zero to a genuinely job-ready foundation, including the portfolio project. Faster with prior software engineering experience; slower if you're building SQL and Python fundamentals from complete scratch alongside everything else.
Frequently Asked Questions
Is data engineering a good fit if I'm coming from a data analyst background?
Yes — see our Data Analyst vs Data Engineer comparison for how the roles differ and what transfers directly from analyst experience.
Do I need a computer science degree for data engineering?
Not strictly — strong demonstrated skill and a solid portfolio project can substitute for formal credentials at many companies, similar to other technical data roles.
Which cloud platform should I specialize in first?
Check job postings in your specific target market — AWS has the broadest general market share, but regional and industry patterns vary meaningfully.
Is Spark necessary for every data engineering role?
Not every role needs deep Spark expertise, but foundational familiarity is increasingly a baseline expectation, particularly for roles at larger companies with genuinely large-scale data.
Bottom Line
Data engineering rewards a structured approach: SQL and Python fundamentals, then data modeling, then pipelines and orchestration, then dbt, distributed computing, and cloud specialization — roughly in that order — followed by a consolidating certificate and a genuine end-to-end portfolio project. Skipping data quality practices and treating pipeline code casually, without version control or testing discipline, are the most common gaps that show up once self-taught engineers reach real production work.