How Large Language Models Work: A Plain-English Guide
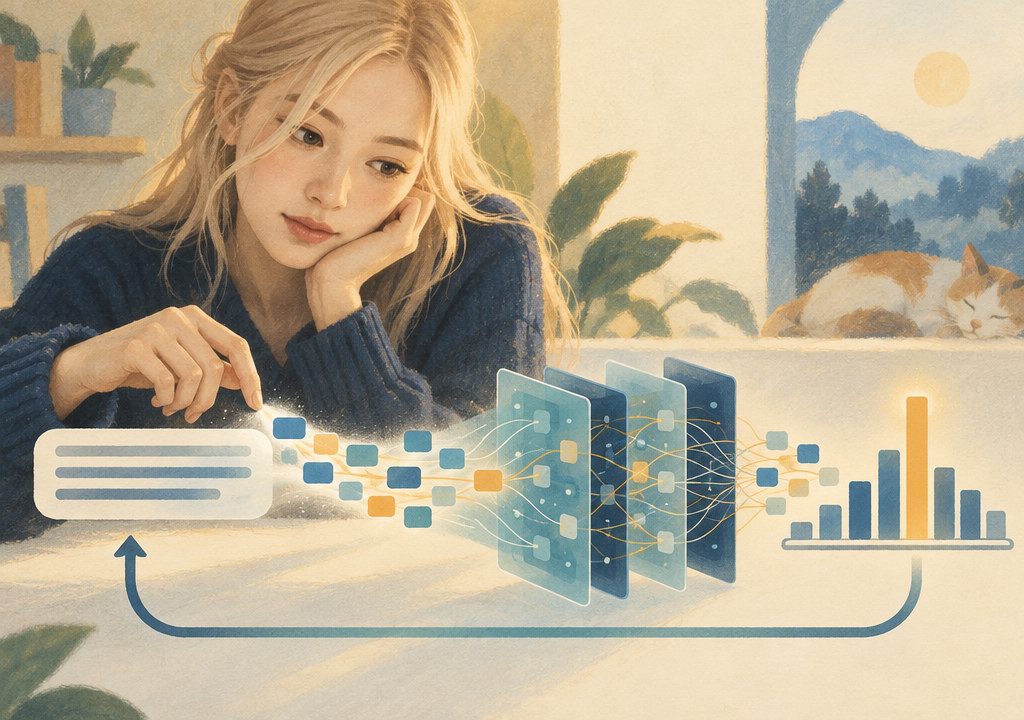
A large language model (LLM) is a very large neural network trained to do one thing: predict the next token (a piece of a word) given all the text before it. It learns to do this by processing enormous amounts of text. Repeated one token at a time, that single skill produces fluent answers, summaries, code and reasoning. Further training on examples and human feedback then turns the raw predictor into a helpful assistant.
You don't need to understand the mathematics to use LLMs well, but a working mental model helps a lot. It explains why they're good at what they're good at, why they make things up, and why techniques like RAG and careful prompting work.
Step 1: Text Becomes Tokens
The model can't read letters directly. Text is split into tokens: common words, parts of words, punctuation. "Understanding" might become "Under" + "standing". Each token maps to an ID number. See Tokens, Context Windows and Temperature for why this matters for cost and limits.
Step 2: Tokens Become Vectors
Each token ID is turned into a long list of numbers, an embedding that represents meaning. Tokens used in similar ways end up with similar vectors. (It's the same idea behind embeddings for search, used inside the model.) The model also adds information about each token's position, because word order matters: "dog bites man" isn't "man bites dog".
Step 3: The Transformer Refines Meaning With Attention
The core of every modern LLM is the transformer architecture, introduced by Google researchers in 2017. It stacks many layers, and each layer lets every token pay attention to the other tokens in the context and update its meaning based on them.
Take the sentence "The bank raised its interest rates". Attention lets "bank" look at "interest rates" and settle on the financial meaning rather than a riverbank. In "She sat on the river bank", the same word attends to "river" and gets a different meaning.
Repeated across dozens of layers, this builds up rich representations: grammar, facts, relationships, the style of the text and what's being asked. The numbers that control all these calculations are the model's parameters, and large models have billions of them.
Step 4: Predict the Next Token, Then Repeat
After the final layer, the model outputs a probability for every token in its vocabulary: how likely each one is to come next.
For "The capital of Vietnam is", the token " Hanoi" gets a very high probability.
A token is chosen, more or less randomly depending on the temperature setting, and added to the text. Then the whole process runs again to predict the following token, and so on until the answer is complete. Every answer you get is produced one token at a time.
How LLMs Are Trained
Pre-training: learning from huge amounts of text
The model starts with random parameters and reads an enormous amount of text: books, websites, code, articles. Again and again it predicts the next token, checks the actual one, and nudges its parameters to be slightly less wrong. No human labels are needed, because the text itself provides the answers. This is self-supervised learning, and it's the expensive part, using very large clusters of GPUs for weeks or months.
The result is a base model: very knowledgeable, but it simply continues text. Ask it a question and it might continue with more questions.
Fine-tuning: learning to be an assistant
The base model is then trained further on examples of instructions paired with good responses (instruction tuning), and refined with human feedback: people rank different answers and the model is trained toward the preferred ones (often called RLHF, reinforcement learning from human feedback). This is what makes it follow instructions, answer helpfully and decline harmful requests.
Reasoning models
Some newer models are also trained to work through a problem step by step before answering, spending extra tokens "thinking". This helps with math, code and multi-step problems, at the cost of more time and tokens.
Why LLMs Hallucinate
Once you know the mechanism, hallucinations make sense. The model is trained to produce plausible next tokens, not to check facts against a database. When it has strong patterns (like "capital of Vietnam"), plausible and true coincide. When it doesn't (an obscure statistic, a specific citation, last week's news), it still produces something plausible-sounding, and plausible isn't the same as true.
Most "weak" items are solved by giving the model tools: a calculator or code execution for math, search or RAG for current facts, databases for business data. That's the idea behind AI agents.
Common Misconceptions
"It looks things up on the internet." A plain LLM doesn't. It generates from patterns learned in training. Some products add web search as a separate tool.
"It remembers my previous conversations." The model itself doesn't learn from your chats in real time. Apps can give it memory by adding past information to the context.
"It understands like a human." It builds powerful internal representations of language and concepts, but it works very differently from human thinking, and it has no built-in way of knowing when it's wrong.
"Bigger is always better." Larger models are generally more capable, but smaller, well-trained models are often good enough and much cheaper for specific tasks.
What does "large" mean in large language model?
Mostly the number of parameters (often billions) and the amount of training data. Both are far larger than earlier language models.
Do LLMs think?
They perform complex computations that can produce reasoning-like step-by-step solutions, especially reasoning-trained models. Whether that counts as "thinking" is a philosophical debate. In practice, treat their reasoning as useful but fallible.
Why do LLMs have a knowledge cut-off?
Pre-training uses data up to a certain date. Anything after it isn't in the model unless it's provided in the prompt, retrieved with RAG, or searched with a tool.
What is a transformer, in one sentence?
A neural network design in which every token uses "attention" to weigh how relevant every other token in the context is, which lets the model capture meaning and long-range relationships in text.
Bottom Line
An LLM turns text into tokens and vectors, refines their meaning through many transformer layers using attention, and predicts the next token, over and over. Pre-training on huge amounts of text gives it knowledge and fluency. Fine-tuning with examples and human feedback makes it a helpful assistant. Because it produces plausible text rather than verified facts, the most reliable uses give it the right context, the right tools and a human check.