RAG vs Fine-Tuning vs Prompt Engineering: Which Should You Use?
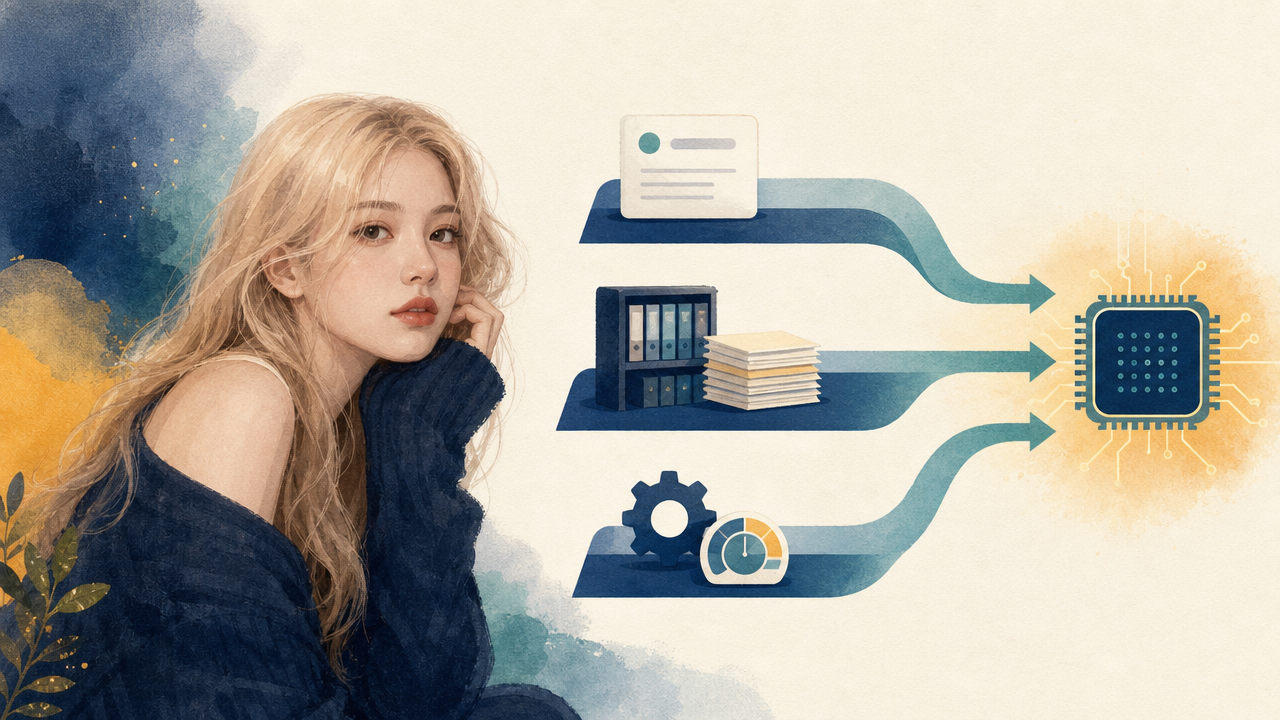
Prompt engineering changes the instructions you give a model. RAG (retrieval-augmented generation) changes the information the model sees, by retrieving relevant documents at question time. Fine-tuning changes the model itself, by training it further on your examples. As a rule: use prompting first, add RAG when the model needs knowledge it doesn't have, and use fine-tuning when you need consistent behavior, style or format that prompting can't reliably produce.
When a team wants an LLM to "know our business", someone usually suggests fine-tuning. Most of the time, that's the wrong first move. This guide explains what each approach actually changes, what it costs, and how to choose.
What Each Approach Changes
Think of an LLM as a capable new employee:
Prompt engineering is giving clear instructions: "write in a formal tone, answer in three bullet points, say you don't know if unsure."
RAG is handing them the right documents to read before answering: "here are the three policy pages that apply to this question."
Fine-tuning is training them for weeks until certain habits are automatic: a house style, a specialized format, a narrow task done the same way every time.
Notice that training someone for weeks is a poor way to give them facts that change every month. That's the core of the decision.
Prompt Engineering
How it works: you write better instructions, examples and structure into the prompt: roles, constraints, output formats, a few worked examples.
Best for: almost everything, as the first step. Format, tone, reasoning steps, using a few examples to show the expected output.
Cost and effort: lowest. Hours to days, and no infrastructure.
Limits: it can't give the model knowledge it doesn't have. Very long prompts cost more on every call (why tokens matter), and complex behaviors may still be inconsistent.
RAG (Retrieval-Augmented Generation)
How it works: your documents are split into chunks, turned into embeddings and stored. At question time the most relevant chunks are retrieved and added to the prompt, so the model answers from them. See What Is RAG? for the full picture.
Best for: knowledge that is private, large or changing, such as policies, product documentation, contracts or internal wikis. It's also the right choice when answers must cite sources or respect access permissions.
Cost and effort: moderate. You build a retrieval pipeline, choose chunking, and evaluate retrieval quality. Updating knowledge is easy: re-index the changed documents.
Limits: answers are only as good as retrieval. If the right chunk isn't found, the model may guess. RAG also doesn't change the model's style or teach it a new skill.
Fine-Tuning
How it works: you train an existing model further on hundreds to thousands of example input–output pairs, so its behavior shifts. Techniques like LoRA (a parameter-efficient method) make this much cheaper than training from scratch, and many providers offer fine-tuning through their APIs.
Best for:
A consistent style, tone or format that prompting can't hold reliably
Narrow, repetitive tasks such as classifying support tickets into your 40 categories, or extracting fields from a specific document type
Making a smaller, cheaper model perform a specific task as well as a larger one (often called distillation), which lowers cost and latency at high volume
Cost and effort: highest. You need good training data (usually the hardest part), evaluation, and retraining whenever requirements change.
Limits: it's a poor way to add facts, especially facts that change. The model may still hallucinate "learned" details, and updating means retraining. It can also overfit on small datasets.
Side-by-Side
Prompt engineering
RAG
Fine-tuning
Changes
Instructions
Information available
Model behavior
Adds new knowledge
Only what fits in the prompt
Yes, and it stays current
Poorly
Changes style / format reliably
Partly
No
Yes
Can cite sources
No
Yes
No
Setup effort
Low
Medium
High
Updating
Edit the prompt
Re-index documents
Retrain
Data needed
A few examples
Your documents
Hundreds to thousands of labeled examples
Decision Guide With Business Examples
Goal
Best approach
"Answer employee questions about our HR policies"
RAG (policies change, and answers should cite the policy)
"Always reply in our brand voice, in Vietnamese, using this template"
Prompting first. Fine-tune only if that's still inconsistent at scale
"Classify 50,000 support tickets a day into our categories, cheaply"
Fine-tune a smaller model, or start with prompting plus examples and compare
"Summarize this week's sales reports"
Prompting, with the data provided in context or retrieved
"Answer questions about our product catalog, which changes daily"
RAG
"A support bot that knows our docs and follows a strict answer format"
RAG + prompting, possibly plus fine-tuning for format
Why Most Teams Combine Them
These aren't competing choices. They're layers. A mature assistant typically uses prompting for instructions and guardrails, RAG for current knowledge and citations, and sometimes fine-tuning for consistent format or lower cost at scale. The usual path is to start simple, measure where it fails, and add the layer that fixes that specific failure.
Common Mistakes
Fine-tuning to add knowledge. Teams train on their documents, then find the model still gets facts wrong and can't be updated easily. Use RAG for facts.
Skipping evaluation. Without a test set of real questions with known good answers, you can't tell whether a change helped.
Blaming the model for a retrieval problem. In RAG systems, check whether the right documents were retrieved before rewriting prompts or switching models.
Over-engineering on day one. A well-written prompt with a handful of examples solves more problems than people expect.
Is RAG better than fine-tuning?
For adding knowledge, especially knowledge that changes, yes. For changing behavior, style or format, or for making a small model good at a narrow task, fine-tuning is the better tool. Many systems use both.
Does fine-tuning reduce hallucinations?
It can reduce some errors on the task it's trained for, but it doesn't reliably stop a model from inventing facts. Grounding answers in retrieved sources (RAG), plus asking the model to say when it doesn't know, is more effective for factual accuracy.
How much data do I need to fine-tune?
It depends on the task and the provider, but typically at least hundreds of high-quality examples, and often thousands. Quality and consistency matter more than quantity.
Can prompt engineering replace fine-tuning completely?
Often, as models improve and context windows grow. Fine-tuning remains valuable for strict formats, very high volume (where a smaller tuned model is cheaper), and specialized behavior that examples in a prompt can't hold consistently.
Bottom Line
Prompting changes the instructions, RAG changes the information and fine-tuning changes the model. Start with prompting, add RAG for private or changing knowledge, and fine-tune only for consistent behavior or cost at scale. Most successful systems combine the three, and they get there by measuring failures rather than guessing.