Star Schema vs Snowflake Schema: Data Modeling for Analysts
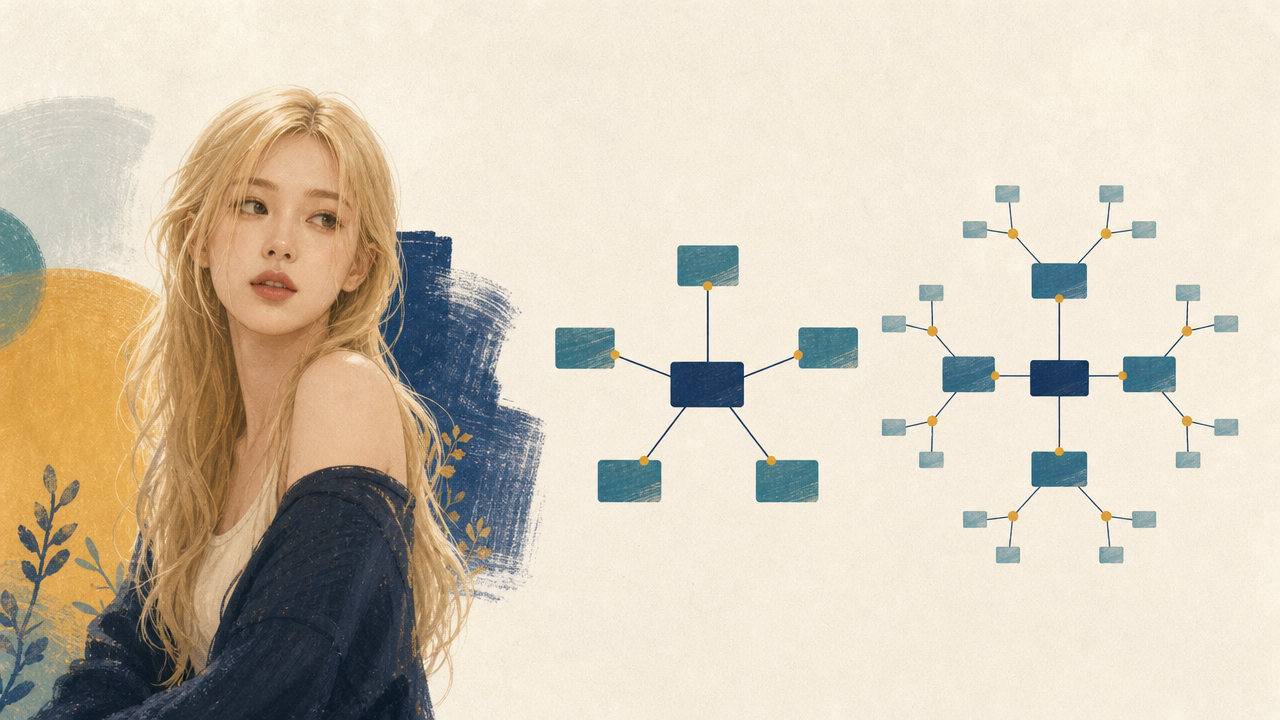
A star schema organizes data into one central fact table (measurable events like sales) surrounded by dimension tables (descriptive context like product, store and date), each joined directly to the fact table. A snowflake schema is a star whose dimension tables are split further into sub-tables, for example product → subcategory → category. Stars are simpler and faster to query. Snowflakes store less repeated data but need more joins.
If you've built a Power BI report on one giant flat table and watched it slow down, or seen totals that didn't add up, the cause was probably the data model rather than the visuals. Dimensional modeling is the skill that fixes that. It's also a named skill in the PL-300 exam ("create fact tables and dimension tables").
Facts vs Dimensions
Every dimensional model starts by sorting data into two kinds of tables.
Fact tables record events you can measure:
Each row is one event: a sale line, an order, a website visit
They contain numeric measures (quantity, amount, cost) and foreign keys pointing to dimensions
They're long (millions of rows) and narrow (few columns)
Dimension tables describe the who, what, where and when:
Each row is one thing: a product, a store, a customer, a day
They contain descriptive attributes you filter and group by (product name, brand, city, month)
They're short (hundreds to thousands of rows) and wide (many columns)
A simple test: if you'd sum or average it, it belongs in a fact table. If you'd filter or group by it, it belongs in a dimension.
A Star Schema: Retail Example
A chain of stores wants to analyze sales. Here's the star:
Notice that dim_product holds subcategoryandcategory in the same table. "Beverages" appears on every beverage product row. That repetition is intentional: it means any product question needs just one join from fact to dimension.
The Same Model as a Snowflake
In a snowflake schema, the product dimension is normalized into a chain:
Now "Beverages" is stored once. But answering "sales by category" needs three joins instead of one.
Side-by-Side
Star schema
Snowflake schema
Dimension design
Denormalized (flattened)
Normalized (split into sub-tables)
Joins per query
Fewer, one per dimension
More, a chain per dimension
Query speed
Usually faster
Usually slower
Storage
Some repeated text
Less duplication
Ease of use
Easy for analysts and BI tools
Harder to navigate
Updating an attribute
Change many rows
Change one row
Best for
BI, dashboards, self-service analytics
Very large or frequently changing hierarchies, some enterprise warehouses
Why Power BI Loves a Star
Microsoft's own Power BI guidance recommends star schemas, and the reasons are practical:
Filters flow cleanly from each dimension to the fact table along one-to-many relationships. That's what makes DAX filter context behave predictably.
Fewer relationships mean a smaller, faster model.
Report builders see a clean field list: "Product", "Store", "Date", instead of dozens of tiny lookup tables.
If your source system gives you snowflaked tables, the usual practice is to flatten them into star dimensions in Power Query (merge subcategory and category into the product table) before loading. You get the storage benefit in the source system and the usability benefit in the report.
The Mistake Most Beginners Make: One Big Flat Table
Many first Power BI reports load one wide table where every sale row repeats the product name, store city, customer segment and so on. It works at first, then problems appear:
The file gets large and slow as rows grow
You can't easily add a second fact table (like targets or inventory) that shares the same products and dates
Time intelligence is awkward without a separate date dimension
Counting distinct customers or products gets error-prone
Splitting that table into facts and dimensions is usually the single biggest improvement you can make to an early report. Our Power BI dashboard tutorial builds the model this way from the start.
Define the Grain First
Before designing any fact table, write down its grain, meaning exactly what one row represents. For example: "one row per product per receipt". Everything follows from that.
Mixing grains is a classic error. Imagine putting monthly sales targets (one row per store per month) into the same table as daily sales lines. Totals double-count or come out blank depending on how you slice them. Different grains belong in separate fact tables that share dimensions.
Other Terms You'll Meet
Surrogate key: a simple integer key (product_key) generated by the warehouse, instead of reusing the source system's product code. It protects the model when source codes change.
Slowly changing dimension (SCD): a method for handling attributes that change over time, like a customer moving city. Type 1 overwrites the old value. Type 2 keeps history with a new row and validity dates.
Conformed dimension: a dimension shared by several fact tables (one dim_date used by sales, targets and inventory), so reports can combine them.
Galaxy (fact constellation) schema: several fact tables sharing dimensions. It's what most real models become.
These ideas come from Ralph Kimball's dimensional modeling approach, which is still the standard reference for analytics data modeling.
Where This Fits in the Modern Stack
In modern warehouses (Snowflake the product, BigQuery, Databricks), storage is cheap, so the storage argument for snowflaking has mostly faded. Many teams build star schemas as the final layer of their transformation pipeline, often with dbt, and point BI tools at those tables. The joins behind every query are the ones from SQL Joins Explained, so a clean star keeps them simple.
Is a star schema normalized or denormalized?
The dimensions are denormalized: attributes like category are repeated on each row so that a query needs fewer joins. The fact table is typically normalized, holding only keys and measures.
Is snowflake schema related to the Snowflake database?
No. The snowflake schema is a modeling pattern named after its branching shape, and it's decades older than the Snowflake cloud platform. You can build either schema in any database.
When should I use a snowflake schema?
When a hierarchy is very large or changes often and must be kept consistent in one place, or when an existing enterprise warehouse already uses it. For BI reporting layers, flatten to a star where you can.
Do I need a date table in a star schema?
Yes, in almost every case. A dedicated date dimension enables time intelligence and consistent fiscal calendars. Power BI's time intelligence functions expect one.
Bottom Line
A star schema puts measurable events in a fact table and descriptive context in flat dimension tables, one join away. A snowflake splits those dimensions further to reduce repetition, at the cost of more joins and complexity. For analytics and Power BI, the star is the default: simpler, faster and easier for everyone who builds reports on top of it.