What Is A/B Testing? A Practical Guide for Data Analysts
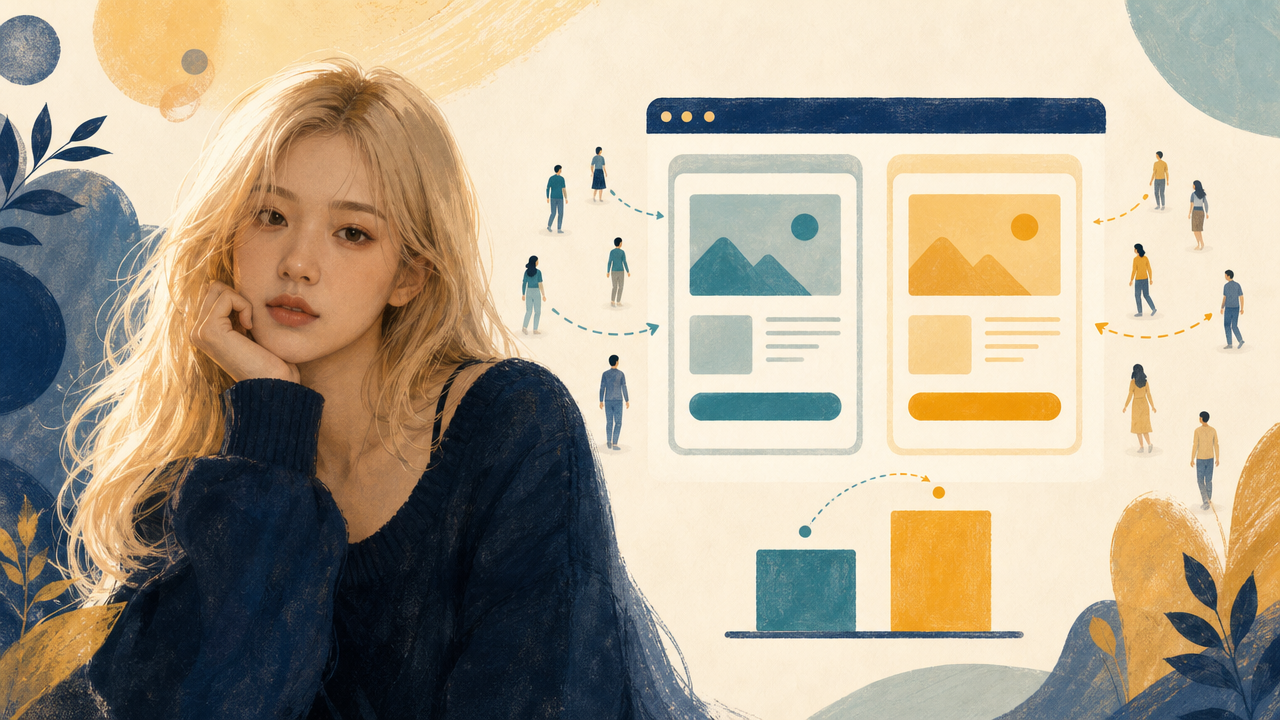
A/B testing is a controlled experiment that randomly splits users into two groups: A (the control, which sees the current version) and B (the variant, which sees a change). You compare a pre-chosen metric, such as conversion rate, between the groups. Because assignment is random, a difference that is big enough to rule out chance can be attributed to the change itself. It's the most practical way to show causation in business data.
Dashboards show what happened. A/B tests show what a change caused. That's why companies test everything from button colors to pricing, and why "how would you design an A/B test?" is a standard analyst interview question.
Why Randomization Is the Whole Point
If you roll out a new checkout page and compare this month's conversion to last month's, anything else that changed (season, marketing, competitors) is mixed in with your change. If you compare users who chose a new feature with users who didn't, you get selection bias.
Random assignment removes both problems. The two groups are the same on average in every way, measured or not, except for the change you made. So when the outcome differs by more than chance would explain, the change caused it.
The Worked Example
An online store wants to test a simplified one-page checkout (B) against the current three-step checkout (A).
Step 1: Write the hypothesis and pick one primary metric
"A one-page checkout will increase purchase conversion rate, because fewer steps mean fewer drop-offs."
Primary metric: conversion rate (purchases ÷ visitors who reached checkout)
Guardrail metrics: average order value and refund rate. These shouldn't get worse.
Choose these before the test starts. Picking the metric after seeing the results is one of the fastest ways to fool yourself.
Step 2: Decide the smallest effect worth detecting and the sample size
Current conversion is 4.0%. The team decides a lift to 4.5% (+0.5 percentage points) would be worth the engineering effort.
The standard sample-size calculation depends on three inputs:
Baseline rate: 4.0%
Minimum detectable effect: +0.5 points
Significance level (α): usually 5%, and power: usually 80%
With those inputs, the answer is roughly 25,500 users per group, about 51,000 in total. With 3,000 checkout visitors a day, the test needs around 17 days. The team plans to run it for three full weeks, so every weekday appears the same number of times.
Online sample-size calculators and Python's statsmodels do this calculation for you. What matters is doing it before you start, not stopping when the results look good.
Step 3: Run the test without peeking
Users are randomly assigned, 50/50, and each user always sees the same version. The team checks that the split is actually close to 50/50. A mismatch (called sample ratio mismatch) signals a bug in the assignment, and the results can't be trusted.
Statistical test: a two-proportion z-test gives z ≈ 3.07, p ≈ 0.002
95% confidence interval for the lift: about +0.20 to +0.90 percentage points
Step 5: Interpret and decide
p ≈ 0.002 means: if the new checkout truly had no effect, a difference this large would happen by chance only about 0.2% of the time. That's well below the 5% threshold, so the result is statistically significant.
The confidence interval is the more useful number for the business. The true lift is plausibly anywhere from +0.20 to +0.90 points. Even the low end is positive, so the change almost certainly helps. The high end shows how much it might help.
Guardrails: average order value and refunds didn't change meaningfully.
Decision: roll out the one-page checkout to everyone.
The Vocabulary, Briefly
Term
Plain meaning
Control / variant
Current version / changed version
Null hypothesis
"The change has no effect." The test asks whether the data is surprising under this assumption
p-value
How surprising the observed difference would be if there were no real effect. Not the probability that B is better
Significance level (α)
The threshold for "surprising enough", usually 5%
Statistical power
The chance of detecting a real effect of the chosen size, usually set at 80%
Confidence interval
The range of effect sizes consistent with the data
Minimum detectable effect
The smallest improvement the test is designed to reliably find
Mistakes That Ruin A/B Tests
Peeking and stopping early. Checking results every day and stopping the moment p drops below 0.05 greatly increases false positives, because random swings cross the line all the time. Fix the sample size in advance, or use methods designed for continuous monitoring (sequential testing).
Testing too many metrics. Check 20 metrics at the 5% level and you'll typically find one "significant" result by pure chance. Name one primary metric in advance and treat the rest as exploratory.
Underpowered tests. Running a test on 2,000 users to detect a 2% relative lift almost always ends in "no significant difference", which gets misread as "no effect".
Ignoring novelty effects. Users sometimes click on something just because it's new. Run tests long enough, at least one or two full weekly cycles, for the novelty to wear off.
Confusing significance with importance. With millions of users, a 0.01-point lift can be "significant" and still not worth shipping. Always judge the size of the effect, not just the p-value.
Using the mean for skewed revenue metrics. Revenue per user is heavily skewed, and a few big spenders can dominate one group. Consider longer tests, robust methods or trimmed metrics. See Mean vs Median vs Mode.
When You Can't Run an A/B Test
Sometimes randomization isn't possible: pricing that must be the same for everyone, legal constraints, or too little traffic. The alternatives are rollouts by region with difference-in-differences analysis, before/after analysis with a comparison group, or qualitative research. They're weaker evidence, so state the limitations clearly. Our correlation vs causation guide covers these methods.
Why This Skill Matters for Your Career
A/B testing sits between diagnostic and prescriptive analytics in the four types of data analytics: it tells you what action works. It comes up often in product and marketing analyst interviews, alongside SQL (see our SQL interview questions). A well-documented A/B analysis on a public dataset is also a strong portfolio piece if you're breaking in without experience.
How long should an A/B test run?
Until it reaches the sample size calculated in advance, and for at least one or two full weekly cycles. Don't stop just because the result looks significant early.
What's a good sample size for an A/B test?
It depends on your baseline rate and the smallest effect you care about. Detecting small lifts on low conversion rates needs tens of thousands of users per group, as in our example. Calculate it before starting.
What does p < 0.05 actually mean?
If the change had no real effect, you'd see a difference at least this large less than 5% of the time. It isn't the probability that the variant is better, and it says nothing about how big the effect is.
What's the difference between A/B testing and multivariate testing?
An A/B test compares whole versions (A vs B, or A vs B vs C). Multivariate testing changes several elements at once to measure each one's effect and how they interact. That needs much more traffic.
Bottom Line
A/B testing uses random assignment to measure what a change actually causes. Write the hypothesis and the primary metric first, calculate the sample size before starting, don't peek, then judge both significance and the size of the effect (the confidence interval). Done properly, it replaces opinions about what works with evidence.