Classification vs Regression: Which Problem Are You Solving?
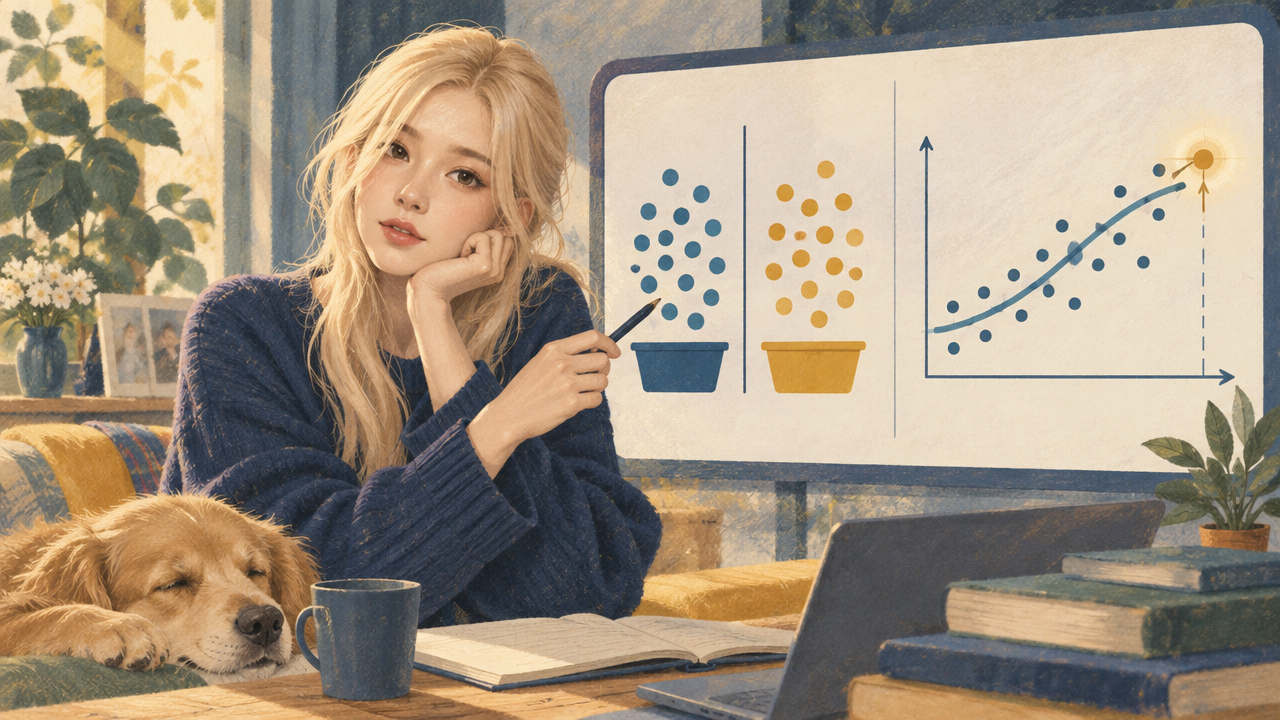
Classification predicts a category: yes/no, spam/not spam, which of five product types. Regression predicts a number on a continuous scale: price, revenue, demand, delivery time. Both are types of supervised learning. The type of target you're predicting decides which algorithms, loss functions and evaluation metrics make sense.
It sounds like a textbook distinction, but getting it wrong, or framing a business problem the wrong way, leads to the wrong metrics and poor decisions. The quick test: look at what you want to predict, and ask whether it's a label or an amount.
Same Data, Two Different Questions
A bank has data on past loans: income, debt, credit history, loan size, and what happened afterwards.
Business question
Target
Problem type
"Will this borrower default?"
Yes / No
Classification (binary)
"Which risk band does this borrower belong to: A, B, C or D?"
Category
Classification (multi-class)
"How much will we lose if this borrower defaults?"
Amount in USD
Regression
"How many days late will this payment be?"
Number of days
Regression
Same data, same features. The target changes the problem.
Classification
Types:
Binary: two classes (churn / no churn, fraud / legitimate)
Multi-class: one of several classes (ticket category, product type)
Multi-label: several labels can apply at once (an article tagged "SQL" and "career")
Output: usually a probability for each class, then a threshold or "highest probability wins" rule turns it into a decision. That threshold is a business choice, as explained in Precision vs Recall.
Common algorithms: logistic regression, decision trees, random forests, gradient boosting (XGBoost, LightGBM), neural networks.
How to evaluate: accuracy (careful with imbalanced data), precision, recall, F1, ROC-AUC, and confusion matrices.
Regression
Output: a number, like 245,000 (price) or 3.2 (days).
Common algorithms: linear regression, regularized regression (ridge, lasso), decision trees, random forests, gradient boosting, neural networks. Many algorithms come in both a classification and a regression version.
How to evaluate:
MAE (mean absolute error): the average size of errors, in the target's own units. Easy to explain.
RMSE (root mean squared error): penalizes large errors more heavily.
R²: the share of the target's variation the model explains.
MAPE (mean absolute percentage error): error as a percentage. It's intuitive, but breaks down when actual values are near zero.
Worked example. A house-price model makes three predictions with errors of +$10K, −$20K and +$5K.
RMSE is higher because the one $20K error weighs more. If big misses are especially costly (like mispricing an expensive house), RMSE reflects that. If every dollar of error matters equally, MAE is easier to interpret.
The Naming Trap: Logistic Regression Is Classification
Despite its name, logistic regression is a classification algorithm. It predicts the probability of a class (a number between 0 and 1), which is then turned into a yes/no decision. The "regression" in the name comes from its mathematical roots. It's a classic interview question and a common source of beginner confusion.
Side-by-Side
Classification
Regression
Predicts
A category
A continuous number
Example
Will the customer churn?
How much will the customer spend next month?
Typical output
Class probabilities, then a label
A numeric value
Metrics
Accuracy, precision, recall, F1, AUC
MAE, RMSE, R², MAPE
Key decision
Where to set the threshold
Which error size is acceptable
Framing the Business Problem
Often you can choose either framing, and the choice matters:
Inventory: predict units demanded (regression), or predict "will this item stock out next week?" (classification). The first supports ordering quantities. The second supports alerts.
Customer value: predict next-year spend (regression), or "high-value or not?" (classification). Turning a number into categories throws information away, so only do it when the decision itself is categorical.
Ratings (1–5 stars): these are ordinal: ordered categories. Treating them as plain classes ignores the order, and treating them as a continuous number assumes equal gaps between them. Both are common and usable, but the choice should be deliberate.
Start from the decision that will be made with the prediction, then choose the framing that serves it.
Common Mistakes
Evaluating classification with accuracy alone on imbalanced data. See Precision vs Recall.
Evaluating regression with R² alone. A good R² can hide large errors on the cases that matter most. Look at MAE or RMSE in real units.
Ignoring skew in regression targets. Revenue and prices are often right-skewed, and a few extreme values dominate RMSE. Consider transforming the target (for example with a log) or using robust metrics. See Mean vs Median vs Mode.
Bucketing a number just to make it a classification problem, and losing precision the business actually needed.
Forgetting about overfitting, which applies equally to both.
Is predicting a probability classification or regression?
It's usually treated as classification: the model estimates the probability of a class, as logistic regression does. The probability is a number, but it describes a categorical outcome.
Can the same algorithm do both?
Many can. Decision trees, random forests, gradient boosting and neural networks all have classification and regression versions, and libraries like scikit-learn provide both (RandomForestClassifier, RandomForestRegressor).
Is forecasting regression?
Forecasting future numbers (next month's sales) is regression over time, but time series needs special care with ordering, seasonality and validation. It's usually treated as its own topic.
Which is easier for beginners?
Linear regression is often taught first because it's intuitive, but most business ML projects are classification problems such as churn, fraud or conversion. Learn both early.
Bottom Line
If you're predicting a label, it's classification. If you're predicting an amount, it's regression. That choice decides your algorithms and, even more importantly, your metrics: precision, recall and thresholds for classification, and MAE or RMSE in real units for regression. Frame the problem around the decision the prediction will support.