What Are Embeddings and Vector Databases? A Plain-English Guide
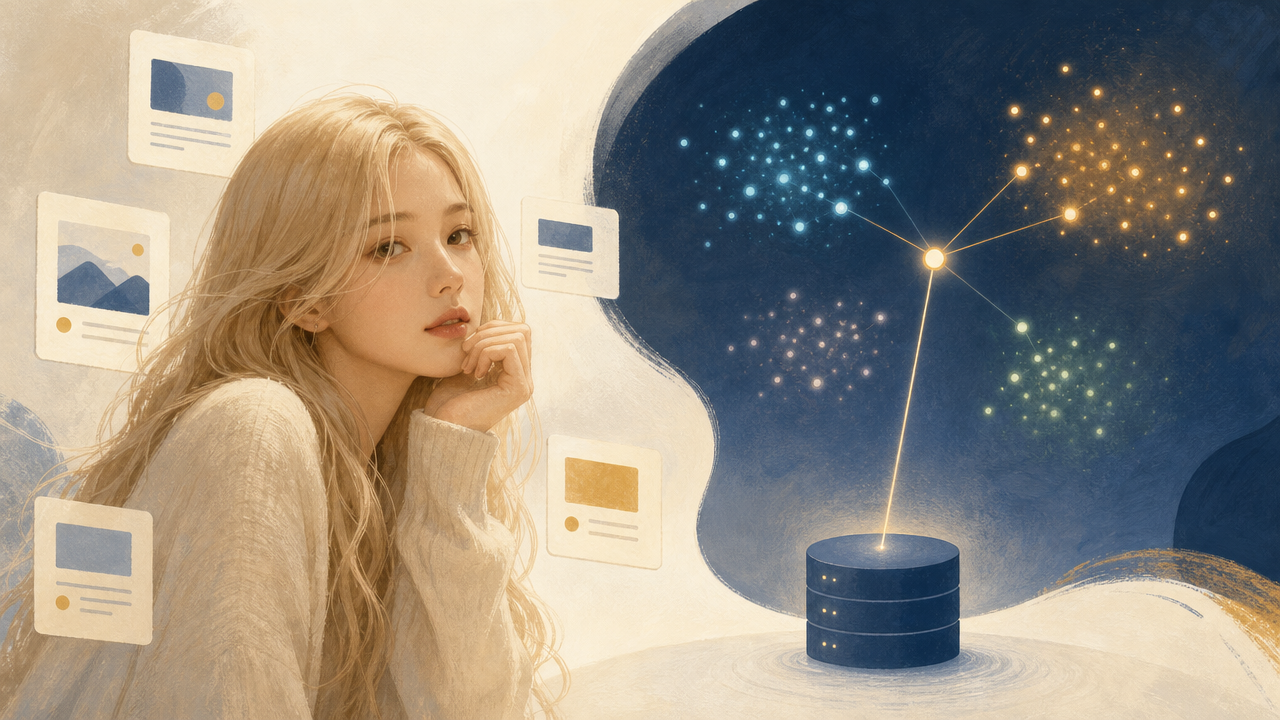
An embedding is a list of numbers (a vector) that represents the meaning of a piece of text, an image or another item, so that things with similar meanings get similar numbers. A vector database stores large numbers of these embeddings and can quickly find the ones closest to a query. Together they let software search by meaning instead of exact keywords, and they're the core machinery behind RAG, semantic search and recommendations.
If you've read our guide to RAG, you've seen the step where the system "retrieves relevant documents". Embeddings and vector databases are how that step works. You don't need advanced math to understand them, just the idea of distance.
The Problem Embeddings Solve
Keyword search matches words, not meaning. A customer types:
"Can I get my money back?"
Your help center has an article titled "Returns and Refund Policy". The two share no important words, so a keyword search may miss it completely. A person immediately sees they're about the same thing.
Embeddings give software a version of that ability. They turn text into numbers in a way that places "get my money back" close to "refund policy", even though the words differ.
How Text Becomes a Vector
An embedding model, a neural network trained on large amounts of text, reads a sentence and outputs a fixed-length list of numbers, for example:
[0.021, -0.113, 0.487, ..., 0.036]
Real embeddings have hundreds to a few thousand numbers (dimensions), depending on the model. No single number means anything on its own. What matters is position: texts with similar meaning end up near each other in this high-dimensional space, and unrelated texts end up far apart.
The embedding model is usually separate from the chat model. Providers such as OpenAI, Google and Cohere offer embedding models through APIs, and there are strong open-source ones you can run yourself.
A Worked Example With Three Dimensions
To see the idea, pretend embeddings had only three numbers:
Text
Vector
Query: "Can I get my money back?"
(0.90, 0.10, 0.20)
Doc A: "Returns and Refund Policy"
(0.85, 0.15, 0.25)
Doc B: "Store Opening Hours"
(0.10, 0.90, 0.30)
To measure how close two vectors are, the most common method is cosine similarity, which compares the direction two vectors point in. A score near 1 means very similar, and near 0 means unrelated.
The refund article wins clearly, without sharing a single keyword with the question. Real systems do exactly this with more dimensions and many more documents.
What a Vector Database Adds
With 50 documents, you could compare the query to every one of them. With 50 million, you can't do that for every search. A vector database is built for this job:
Stores embeddings along with the original text and metadata (source, date, author, access rights)
Indexes them with approximate nearest neighbor (ANN) algorithms such as HNSW, which find the closest vectors in milliseconds without checking every one. The trade-off is that results are very close to perfect rather than guaranteed perfect.
Filters by metadata, for example "only documents from 2026 that this user may see"
Common options:
Type
Examples
Good for
Extension to an existing database
PostgreSQL + pgvector
Teams already using Postgres; moderate scale
Dedicated vector database
Pinecone, Weaviate, Qdrant, Milvus
Large scale, managed or self-hosted
Lightweight / local
Chroma, FAISS (a library)
Prototypes, notebooks, small apps
Built into platforms
Search features in cloud warehouses and search engines
Keeping everything in one stack
For learning and small projects, a local option like Chroma or pgvector is plenty. Choose tools based on your scale, and don't let vendor comparisons slow you down at the start.
How It All Fits Together in RAG
Chunk your documents into passages, often a few hundred tokens each (what's a token?)
Embed each chunk and store it in the vector database
When a user asks a question, embed the question with the same embedding model
Retrieve the most similar chunks
Send those chunks plus the question to the LLM, which writes an answer grounded in them
Frameworks like LangChain and LlamaIndex handle much of this plumbing. See LangChain vs LlamaIndex.
Beyond RAG: Other Uses
Semantic search: help centers, internal wikis, product catalogs
Recommendations: "customers who liked this also liked…" based on similarity of product or content embeddings
Deduplication: finding near-duplicate support tickets or product listings written differently
Clustering: grouping thousands of customer reviews by topic, a common unsupervised use
Classification: using embeddings as features for a regular ML model
Common Mistakes
Mixing embedding models. Vectors from different models live in different "spaces" and can't be compared. If you switch models, re-embed everything.
Bad chunking. Chunks that are too big blur several topics together. Chunks that are too small lose context. Chunking choices often affect answer quality more than the choice of database.
Relying on vectors alone. Embeddings are weak on exact matches like product codes, names and error numbers. Hybrid search, which combines keyword and vector search, usually works better in production.
Ignoring language. If your content is in Vietnamese or several languages, choose an embedding model that handles those languages well and test it on real queries.
Skipping evaluation. Build a small set of real questions with known correct documents and measure whether retrieval finds them before you tune anything else.
Are embeddings the same as tokens?
No. Tokens are the pieces text is split into. An embedding is a vector representing meaning, which can cover a single token, a sentence or a whole document. Embedding models do use tokens internally.
Do I need a vector database to use embeddings?
Not at small scale. A few thousand vectors can be searched in memory with a library like NumPy or FAISS. A vector database becomes worthwhile when you need scale, persistence, metadata filtering and multiple users.
How much do embeddings cost?
Embedding API calls are usually far cheaper per token than chat-model calls, and you embed each document once (plus queries). Storage and re-embedding after a model change are the costs people tend to forget.
What is cosine similarity in simple terms?
A measure of whether two vectors point in the same direction. A value of 1 means the same direction (very similar meaning), 0 means unrelated, and negative values mean opposite directions.
Bottom Line
Embeddings turn meaning into numbers, so software can measure how similar two pieces of text are. Vector databases store those numbers and find the closest matches fast. They power retrieval in RAG and a range of search and recommendation features. Choose one embedding model and use it consistently, chunk carefully, add keyword search for exact terms, and test retrieval on real questions.