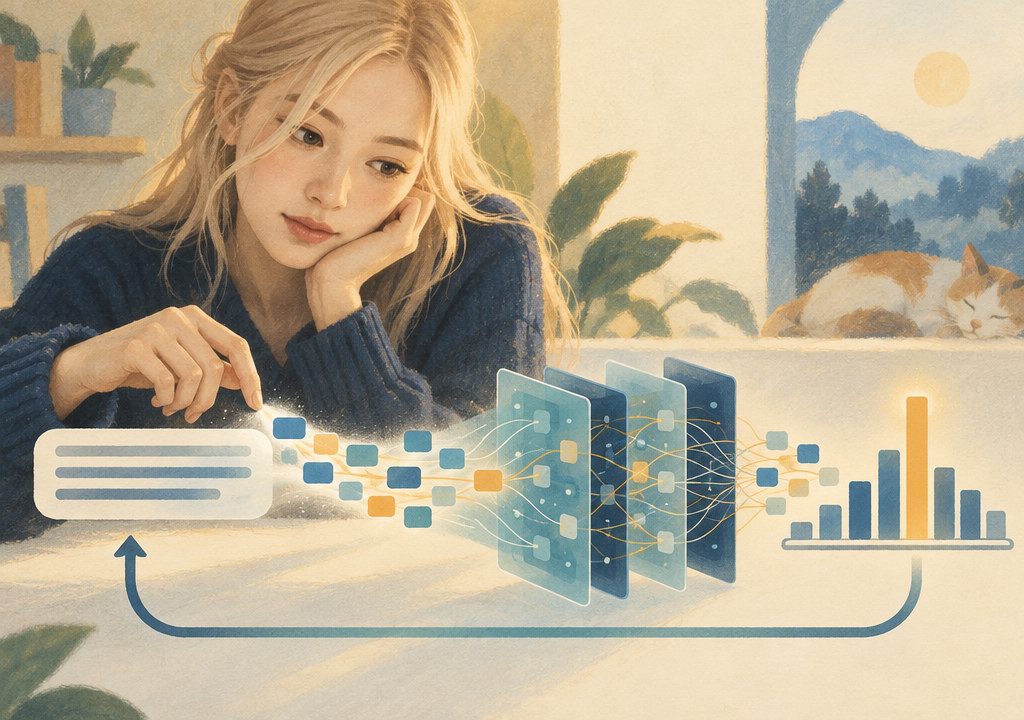
How Large Language Models Work: A Plain-English Guide
How large language models work, step by step - tokens, embeddings, transformers and attention, next-token prediction, training, and why they hallucinate.
Insights and guides to help you master data, BI, and analytics.
How large language models work, step by step - tokens, embeddings, transformers and attention, next-token prediction, training, and why they hallucinate.
RAG vs fine-tuning vs prompt engineering compared - what each changes, cost and effort, a decision guide with business examples, and why teams combine them.
Embeddings and vector databases explained simply - how text becomes numbers, how cosine similarity finds meaning, and why they power RAG and semantic search.
What tokens, context windows and temperature mean in ChatGPT, Claude and Gemini - how they affect cost, accuracy and output, with a worked cost example.
Do you need a machine learning background to build LLM applications? What's actually required, and what you can safely learn along the way.
LangChain vs LlamaIndex compared - what each framework is actually built for, and which one to learn first for your specific LLM project.
RAG explained in plain English for data professionals - what it actually does, why it matters for LLM apps, and how it differs from fine-tuning.
DeepLearning.AI's Generative AI with Large Language Models course reviewed - technical depth, real prerequisites, and who should take it.
A step-by-step generative AI learning path - foundational concepts, then RAG and fine-tuning, with course recommendations for each stage.